
Self-hosted AI Starter Kit
Local AI environment with n8n and LLMs
14.6k|stable
n8n with 400+ integrations — Low-code platform for building AI workflows with pre-built connectors.
Ollama local LLM support — Run large language models locally without external API calls.
Qdrant vector database — Store and query embeddings for RAG and semantic search.
GPU acceleration — Profiles for NVIDIA, AMD, and Apple Silicon processors.
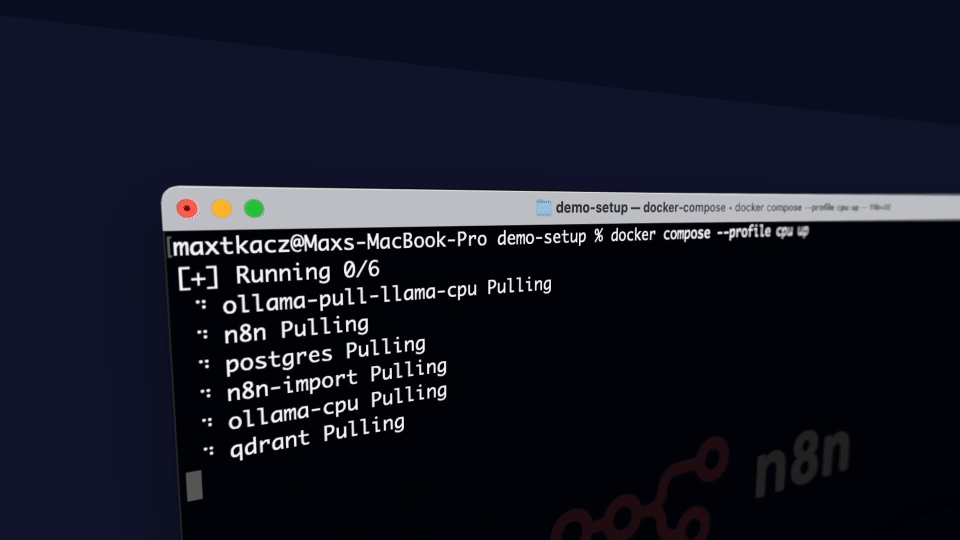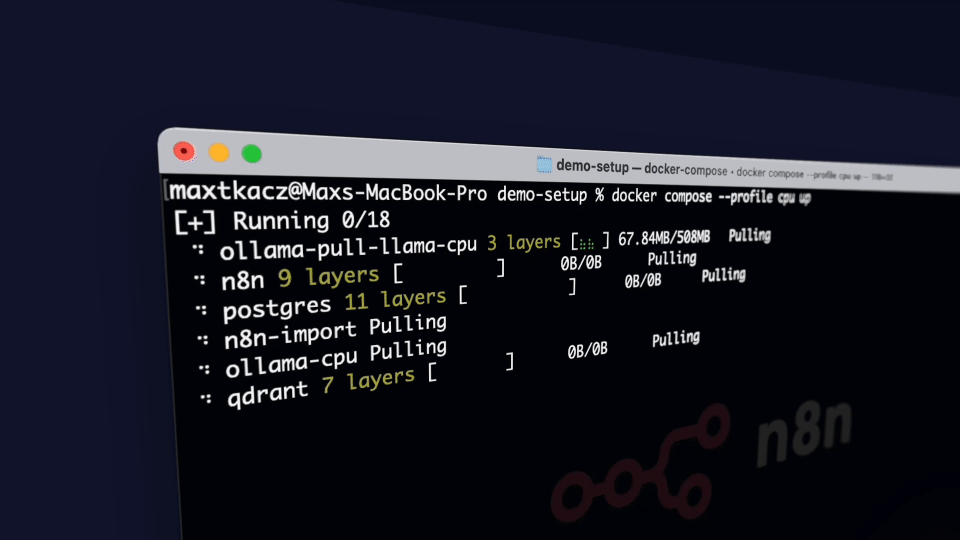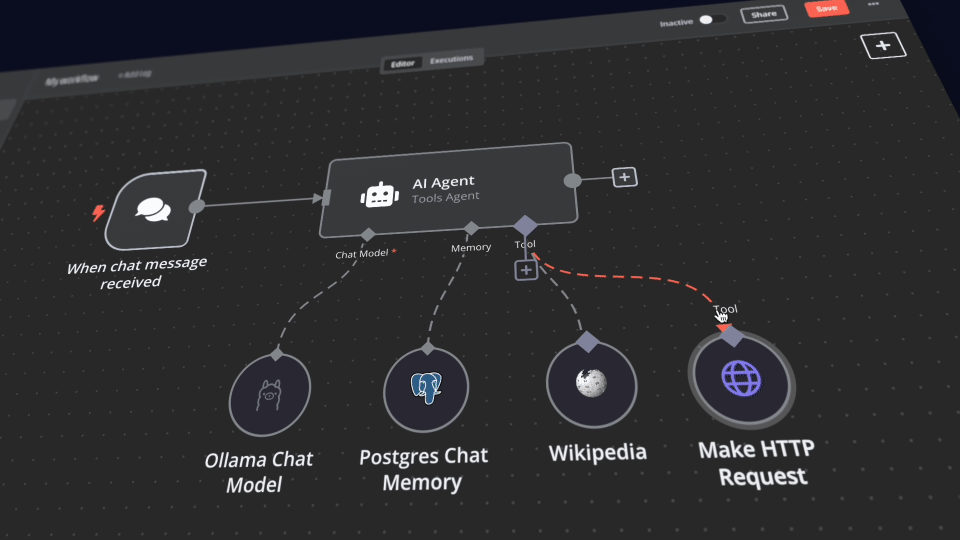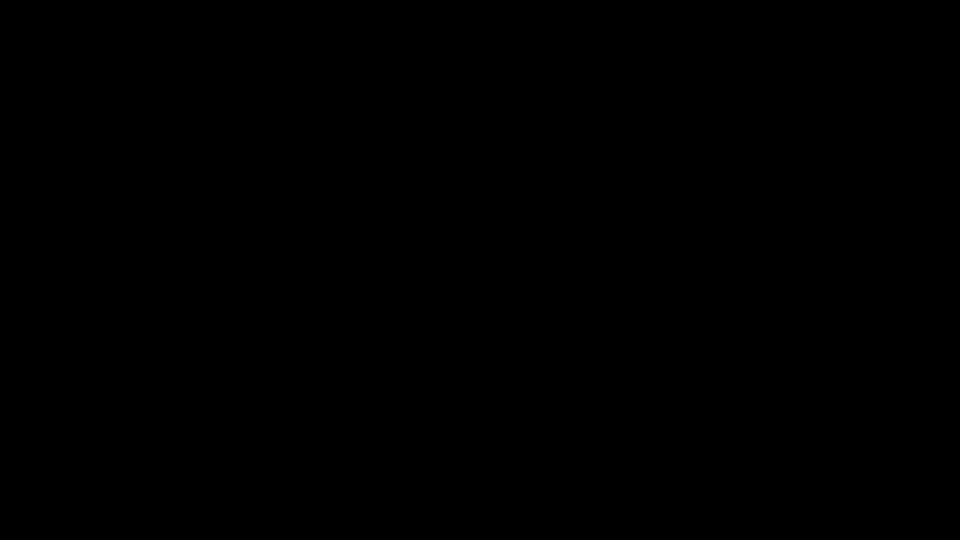
Pre-configured Docker Compose stack combining n8n, Ollama, Qdrant, and PostgreSQL for building self-hosted AI workflows. Includes example workflows for agents, document analysis, and Slack bots. Supports GPU acceleration across NVIDIA, AMD, and Apple Silicon platforms.
Docker and Docker Compose


